
yolov26改进 | 细节创新篇 | iAFF迭代注意力特征融合改进C3k2助力yolov26有效涨点(附独家网络结构图

开始讲解之前推荐一下我的专栏,本专栏的内容支持(分类、检测、分割、追踪、关键点检测),专栏目前为限时折扣,欢迎大家订阅本专栏,本专栏每周更新5-7篇最新机制,更有包含我所有改进的文件和交流群提供给大家,本人定期在群内分享发表论文方法和经验。
一、本文介绍
本文给大家带来的最新改进机制是iAFF(迭代注意力特征融合),其主要思想是通过改善特征融合过程来提高检测精度。传统的特征融合方法如加法或串联简单,未考虑到特定对象的融合适用性。iAFF通过引入多尺度通道注意力模块(我个人觉得这个改进机制就算融合了注意力机制的求和操作),更好地整合不同尺度和语义不一致的特征。该方法属于细节上的改进,并不影响任何其它的模块,非常适合大家进行融合改进,单独使用也是有一定的涨点效果。
欢迎大家订阅我的专栏一起学习YOLO!

专栏链接:YOLOv26有效涨点专栏包含:Conv、注意力机制、主干/Backbone、损失函数、优化器、后处理等改进机制
目录
二、iAFF的基本框架原理
官方论文地址: 官方论文地址点击即可跳转
官方代码地址: 官方代码地址点击即可跳转
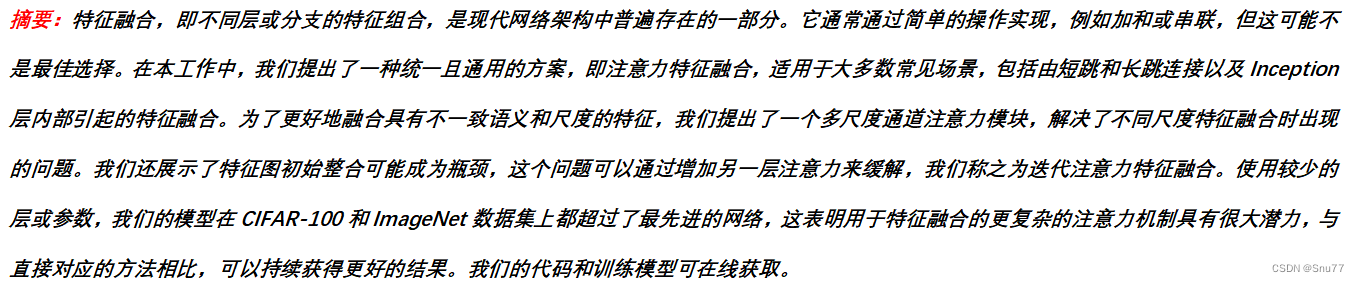
iAFF的主要思想在于通过更精细的注意力机制来改善特征融合,从而增强卷积神经网络。它不仅处理了由于尺度和语义不一致而引起的特征融合问题,还引入了多尺度通道注意力模块,提供了一种统一且通用的特征融合方案。此外,iAFF通过迭代注意力特征融合来解决特征图初始整合可能成为的瓶颈。这种方法使得模型即使在层数或参数较少的情况下,也能取得到较好的效果。
iAFF的创新点主要包括:
1. 注意力特征融合:提出了一种新的特征融合方式,利用注意力机制来改善传统的简单特征融合方法(如加和或串联)。
2. 多尺度通道注意力模块:解决了在不同尺度上融合特征时出现的问题,特别是语义和尺度不一致的特征融合问题。
3. 迭代注意力特征融合(iAFF):通过迭代地应用注意力机制来改善特征图的初步整合,克服了初步整合可能成为性能瓶颈的问题。

这张图片是关于所提出的AFF(注意力特征融合)和iAFF(迭代注意力特征融合)的示意图。图中展示了两种结构:
(a) AFF: 展示了一个通过多尺度通道注意力模块(MS-CAM)来融合不同特征的基本框架。特征图X和Y通过MS-CAM和其他操作融合,产生输出Z。
(b) iAFF: 与AFF类似,但添加了迭代结构。在这里,输出Z回馈到输入,与X和Y一起再次经过MS-CAM和融合操作,以进一步细化特征融合过程。
(这两种方法都是文章中提出的我仅使用了iAFF也就是更复杂的版本,大家对于AFF有兴趣的可以按照我的该法进行相似添加即可)
三、iAFF的核心代码
使用方式看章节四!
import torch
import torch.nn as nn

__all__ = ['C3k2_iAFF']


def autopad(k, p=None, d=1):  # kernel, padding, dilation
    """Pad to 'same' shape outputs."""
    if d > 1:
        k = d * (k - 1) + 1 if isinstance(k, int) else [d * (x - 1) + 1 for x in k]  # actual kernel-size
    if p is None:
        p = k // 2 if isinstance(k, int) else [x // 2 for x in k]  # auto-pad
    return p


class Conv(nn.Module):
    """Standard convolution with args(ch_in, ch_out, kernel, stride, padding, groups, dilation, activation)."""
    default_act = nn.SiLU()  # default activation

    def __init__(self, c1, c2, k=1, s=1, p=None, g=1, d=1, act=True):
        """Initialize Conv layer with given arguments including activation."""
        super().__init__()
        self.conv = nn.Conv2d(c1, c2, k, s, autopad(k, p, d), groups=g, dilation=d, bias=False)
        self.bn = nn.BatchNorm2d(c2)
        self.act = self.default_act if act is True else act if isinstance(act, nn.Module) else nn.Identity()

    def forward(self, x):
        """Apply convolution, batch normalization and activation to input tensor."""
        return self.act(self.bn(self.conv(x)))

    def forward_fuse(self, x):
        """Perform transposed convolution of 2D data."""
        return self.act(self.conv(x))


class iAFF(nn.Module):
    '''
    多特征融合 iAFF
    '''

    def __init__(self, channels=64, r=2):
        super(iAFF, self).__init__()
        inter_channels = int(channels // r)

        # 本地注意力
        self.local_att = nn.Sequential(
            nn.Conv2d(channels, inter_channels, kernel_size=1, stride=1, padding=0),
            nn.BatchNorm2d(inter_channels),
            nn.ReLU(inplace=True),
            nn.Conv2d(inter_channels, channels, kernel_size=1, stride=1, padding=0),
            nn.BatchNorm2d(channels),
        )

        # 全局注意力
        self.global_att = nn.Sequential(
            nn.AdaptiveAvgPool2d(1),
            nn.Conv2d(channels, inter_channels, kernel_size=1, stride=1, padding=0),
            nn.ReLU(inplace=True),
            nn.Conv2d(inter_channels, channels, kernel_size=1, stride=1, padding=0),
        )

        # 第二次本地注意力
        self.local_att2 = nn.Sequential(
            nn.Conv2d(channels, inter_channels, kernel_size=1, stride=1, padding=0),
            nn.BatchNorm2d(inter_channels),
            nn.ReLU(inplace=True),
            nn.Conv2d(inter_channels, channels, kernel_size=1, stride=1, padding=0),
            nn.BatchNorm2d(channels),
        )
        # 第二次全局注意力
        self.global_att2 = nn.Sequential(
            nn.AdaptiveAvgPool2d(1),
            nn.Conv2d(channels, inter_channels, kernel_size=1, stride=1, padding=0),
            nn.BatchNorm2d(inter_channels),
            nn.ReLU(inplace=True),
            nn.Conv2d(inter_channels, channels, kernel_size=1, stride=1, padding=0),
            nn.BatchNorm2d(channels),
        )

        self.sigmoid = nn.Sigmoid()

    def forward(self, x, residual):

        xa = x + residual
        xl = self.local_att(xa)
        xg = self.global_att(xa)
        xlg = xl + xg
        wei = self.sigmoid(xlg)
        xi = x * wei + residual * (1 - wei)

        xl2 = self.local_att2(xi)
        xg2 = self.global_att(xi)
        xlg2 = xl2 + xg2
        wei2 = self.sigmoid(xlg2)
        xo = x * wei2 + residual * (1 - wei2)
        return xo


class AFF(nn.Module):
    '''
    多特征融合 AFF
    '''

    def __init__(self, channels=64, r=4):
        super(AFF, self).__init__()
        inter_channels = int(channels // r)

        self.local_att = nn.Sequential(
            nn.Conv2d(channels, inter_channels, kernel_size=1, stride=1, padding=0),
            nn.BatchNorm2d(inter_channels),
            nn.ReLU(inplace=True),
            nn.Conv2d(inter_channels, channels, kernel_size=1, stride=1, padding=0),
            nn.BatchNorm2d(channels),
        )

        self.global_att = nn.Sequential(
            nn.AdaptiveAvgPool2d(1),
            nn.Conv2d(channels, inter_channels, kernel_size=1, stride=1, padding=0),
            nn.BatchNorm2d(inter_channels),
            nn.ReLU(inplace=True),
            nn.Conv2d(inter_channels, channels, kernel_size=1, stride=1, padding=0),
            nn.BatchNorm2d(channels),
        )

        self.sigmoid = nn.Sigmoid()

    def forward(self, x, residual):
        xa = x + residual
        xl = self.local_att(xa)
        xg = self.global_att(xa)
        xlg = xl + xg
        wei = self.sigmoid(xlg)

        xo = 2 * x * wei + 2 * residual * (1 - wei)
        return xo

class Bottleneck_iAFF(nn.Module):
    """Standard bottleneck."""

    def __init__(self, c1, c2, shortcut=True, g=1, k=(3, 3), e=0.5):
        """Initializes a bottleneck module with given input/output channels, shortcut option, group, kernels, and
        expansion.
        """
        super().__init__()
        c_ = int(c2 * e)  # hidden channels
        self.cv1 = Conv(c1, c_, k[0], 1)
        self.cv2 = Conv(c_, c2, k[1], 1, g=g)
        self.add = shortcut and c1 == c2
        self.iAFF = iAFF(c2)
    def forward(self, x):
        """'forward()' applies the YOLO FPN to input data."""
        if self.add:
           results = self.iAFF(x , self.cv2(self.cv1(x)))
        else:
            results = self.cv2(self.cv1(x))
        return results

class Bottleneck_AFF(nn.Module):
    """Standard bottleneck."""

    def __init__(self, c1, c2, shortcut=True, g=1, k=(3, 3), e=0.5):
        """Initializes a bottleneck module with given input/output channels, shortcut option, group, kernels, and
        expansion.
        """
        super().__init__()
        c_ = int(c2 * e)  # hidden channels
        self.cv1 = Conv(c1, c_, k[0], 1)
        self.cv2 = Conv(c_, c2, k[1], 1, g=g)
        self.add = shortcut and c1 == c2
        self.AFF = AFF(c2)

    def forward(self, x):
        """'forward()' applies the YOLO FPN to input data."""
        if self.add:
            results = self.AFF(x, self.cv2(self.cv1(x)))
        else:
            results = self.cv2(self.cv1(x))
        return results


class Bottleneck(nn.Module):
    """Standard bottleneck."""

    def __init__(self, c1, c2, shortcut=True, g=1, k=(3, 3), e=0.5):
        """Initializes a standard bottleneck module with optional shortcut connection and configurable parameters."""
        super().__init__()
        c_ = int(c2 * e)  # hidden channels
        self.cv1 = Conv(c1, c_, k[0], 1)
        self.cv2 = Conv(c_, c2, k[1], 1, g=g)
        self.add = shortcut and c1 == c2

    def forward(self, x):
        """Applies the YOLO FPN to input data."""
        return x + self.cv2(self.cv1(x)) if self.add else self.cv2(self.cv1(x))


class C2f(nn.Module):
    """Faster Implementation of CSP Bottleneck with 2 convolutions."""

    def __init__(self, c1, c2, n=1, shortcut=False, g=1, e=0.5):
        """Initializes a CSP bottleneck with 2 convolutions and n Bottleneck blocks for faster processing."""
        super().__init__()
        self.c = int(c2 * e)  # hidden channels
        self.cv1 = Conv(c1, 2 * self.c, 1, 1)
        self.cv2 = Conv((2 + n) * self.c, c2, 1)  # optional act=FReLU(c2)
        self.m = nn.ModuleList(Bottleneck(self.c, self.c, shortcut, g, k=((3, 3), (3, 3)), e=1.0) for _ in range(n))

    def forward(self, x):
        """Forward pass through C2f layer."""
        y = list(self.cv1(x).chunk(2, 1))
        y.extend(m(y[-1]) for m in self.m)
        return self.cv2(torch.cat(y, 1))

    def forward_split(self, x):
        """Forward pass using split() instead of chunk()."""
        y = list(self.cv1(x).split((self.c, self.c), 1))
        y.extend(m(y[-1]) for m in self.m)
        return self.cv2(torch.cat(y, 1))


class C3(nn.Module):
    """CSP Bottleneck with 3 convolutions."""

    def __init__(self, c1, c2, n=1, shortcut=True, g=1, e=0.5):
        """Initialize the CSP Bottleneck with given channels, number, shortcut, groups, and expansion values."""
        super().__init__()
        c_ = int(c2 * e)  # hidden channels
        self.cv1 = Conv(c1, c_, 1, 1)
        self.cv2 = Conv(c1, c_, 1, 1)
        self.cv3 = Conv(2 * c_, c2, 1)  # optional act=FReLU(c2)
        self.m = nn.Sequential(*(Bottleneck(c_, c_, shortcut, g, k=((1, 1), (3, 3)), e=1.0) for _ in range(n)))

    def forward(self, x):
        """Forward pass through the CSP bottleneck with 2 convolutions."""
        return self.cv3(torch.cat((self.m(self.cv1(x)), self.cv2(x)), 1))


class C3k(C3):
    """C3k is a CSP bottleneck module with customizable kernel sizes for feature extraction in neural networks."""

    def __init__(self, c1, c2, n=1, shortcut=True, g=1, e=0.5, k=3):
        """Initializes the C3k module with specified channels, number of layers, and configurations."""
        super().__init__(c1, c2, n, shortcut, g, e)
        c_ = int(c2 * e)  # hidden channels
        # self.m = nn.Sequential(*(RepBottleneck(c_, c_, shortcut, g, k=(k, k), e=1.0) for _ in range(n)))
        self.m = nn.Sequential(*(Bottleneck(c_, c_, shortcut, g, k=(k, k), e=1.0) for _ in range(n)))

class Attention_YOLOv26(nn.Module):
    """Attention module that performs self-attention on the input tensor.

    Args:
        dim (int): The input tensor dimension.
        num_heads (int): The number of attention heads.
        attn_ratio (float): The ratio of the attention key dimension to the head dimension.

    Attributes:
        num_heads (int): The number of attention heads.
        head_dim (int): The dimension of each attention head.
        key_dim (int): The dimension of the attention key.
        scale (float): The scaling factor for the attention scores.
        qkv (Conv): Convolutional layer for computing the query, key, and value.
        proj (Conv): Convolutional layer for projecting the attended values.
        pe (Conv): Convolutional layer for positional encoding.
    """

    def __init__(self, dim: int, num_heads: int = 8, attn_ratio: float = 0.5):
        """Initialize multi-head attention module.

        Args:
            dim (int): Input dimension.
            num_heads (int): Number of attention heads.
            attn_ratio (float): Attention ratio for key dimension.
        """
        super().__init__()
        self.num_heads = num_heads
        self.head_dim = dim // num_heads
        self.key_dim = int(self.head_dim * attn_ratio)
        self.scale = self.key_dim**-0.5
        nh_kd = self.key_dim * num_heads
        h = dim + nh_kd * 2
        self.qkv = Conv(dim, h, 1, act=False)
        self.proj = Conv(dim, dim, 1, act=False)
        self.pe = Conv(dim, dim, 3, 1, g=dim, act=False)

    def forward(self, x: torch.Tensor) -> torch.Tensor:
        """Forward pass of the Attention module.

        Args:
            x (torch.Tensor): The input tensor.

        Returns:
            (torch.Tensor): The output tensor after self-attention.
        """
        B, C, H, W = x.shape
        N = H * W
        qkv = self.qkv(x)
        q, k, v = qkv.view(B, self.num_heads, self.key_dim * 2 + self.head_dim, N).split(
            [self.key_dim, self.key_dim, self.head_dim], dim=2
        )

        attn = (q.transpose(-2, -1) @ k) * self.scale
        attn = attn.softmax(dim=-1)
        x = (v @ attn.transpose(-2, -1)).view(B, C, H, W) + self.pe(v.reshape(B, C, H, W))
        x = self.proj(x)
        return x


class PSABlock(nn.Module):
    """PSABlock class implementing a Position-Sensitive Attention block for neural networks.

    This class encapsulates the functionality for applying multi-head attention and feed-forward neural network layers
    with optional shortcut connections.

    Attributes:
        attn (Attention): Multi-head attention module.
        ffn (nn.Sequential): Feed-forward neural network module.
        add (bool): Flag indicating whether to add shortcut connections.

    Methods:
        forward: Performs a forward pass through the PSABlock, applying attention and feed-forward layers.

    """

    def __init__(self, c: int, attn_ratio: float = 0.5, num_heads: int = 4, shortcut: bool = True) -> None:
        """Initialize the PSABlock.

        Args:
            c (int): Input and output channels.
            attn_ratio (float): Attention ratio for key dimension.
            num_heads (int): Number of attention heads.
            shortcut (bool): Whether to use shortcut connections.
        """
        super().__init__()

        self.attn = Attention_YOLOv26(c, attn_ratio=attn_ratio, num_heads=num_heads)
        self.ffn = nn.Sequential(Conv(c, c * 2, 1), Conv(c * 2, c, 1, act=False))
        self.add = shortcut

    def forward(self, x: torch.Tensor) -> torch.Tensor:
        """Execute a forward pass through PSABlock.

        Args:
            x (torch.Tensor): Input tensor.

        Returns:
            (torch.Tensor): Output tensor after attention and feed-forward processing.
        """
        x = x + self.attn(x) if self.add else self.attn(x)
        x = x + self.ffn(x) if self.add else self.ffn(x)
        return x

class C3k(C3):
    """C3k is a CSP bottleneck module with customizable kernel sizes for feature extraction in neural networks."""

    def __init__(self, c1: int, c2: int, n: int = 1, shortcut: bool = True, g: int = 1, e: float = 0.5, k: int = 3):
        """Initialize C3k module.

        Args:
            c1 (int): Input channels.
            c2 (int): Output channels.
            n (int): Number of Bottleneck blocks.
            shortcut (bool): Whether to use shortcut connections.
            g (int): Groups for convolutions.
            e (float): Expansion ratio.
            k (int): Kernel size.
        """
        super().__init__(c1, c2, n, shortcut, g, e)
        c_ = int(c2 * e)  # hidden channels
        # self.m = nn.Sequential(*(RepBottleneck(c_, c_, shortcut, g, k=(k, k), e=1.0) for _ in range(n)))
        self.m = nn.Sequential(*(Bottleneck(c_, c_, shortcut, g, k=(k, k), e=1.0) for _ in range(n)))


class C3k_iAFF(C3):
    """C3k is a CSP bottleneck module with customizable kernel sizes for feature extraction in neural networks."""

    def __init__(self, c1, c2, n=1, shortcut=True, g=1, e=0.5, k=3):
        """Initializes the C3k module with specified channels, number of layers, and configurations."""
        super().__init__(c1, c2, n, shortcut, g, e)
        c_ = int(c2 * e)  # hidden channels
        # self.m = nn.Sequential(*(RepBottleneck(c_, c_, shortcut, g, k=(k, k), e=1.0) for _ in range(n)))
        self.m = nn.Sequential(*(Bottleneck_iAFF(c_, c_, shortcut, g, k=(k, k), e=1.0) for _ in range(n)))


class C3k2_iAFF(C2f):
    """Faster Implementation of CSP Bottleneck with 2 convolutions."""

    def __init__(
        self,
        c1: int,
        c2: int,
        n: int = 1,
        c3k: bool = False,
        e: float = 0.5,
        attn: bool = False,
        g: int = 1,
        shortcut: bool = True,
    ):
        """Initialize C3k2 modu
        Args:
            c1 (int): Input channels.
            c2 (int): Output channels.
            n (int): Number of blocks.
            c3k (bool): Whether to use C3k blocks.
            e (float): Expansion ratio.
            attn (bool): Whether to use attention blocks.
            g (int): Groups for convolutions.
            shortcut (bool): Whether to use shortcut connections.
        """
        super().__init__(c1, c2, n, shortcut, g, e)
        self.m = nn.ModuleList(
            nn.Sequential(
                Bottleneck_iAFF(self.c, self.c, shortcut, g),
                PSABlock(self.c, attn_ratio=0.5, num_heads=max(self.c // 64, 1)),
            )
            if attn
            else C3k_iAFF(self.c, self.c, 2, shortcut, g)
            if c3k
            else Bottleneck_iAFF(self.c, self.c, shortcut, g)
            for _ in range(n)
        )


if __name__ == '__main__':
    from thop import profile, clever_format
    inp1= torch.rand(1,48,256,256)
    model = C3k2_iAFF(48,48)
    out = model(inp1)
print(out.shape)四、手把手教你添加C3k2iAFF
下面的步骤如果你不会或者不想麻烦操作,可以联系作者获得本专栏添加所有项目文件的源代码,可直接训练.
4.1 修改一
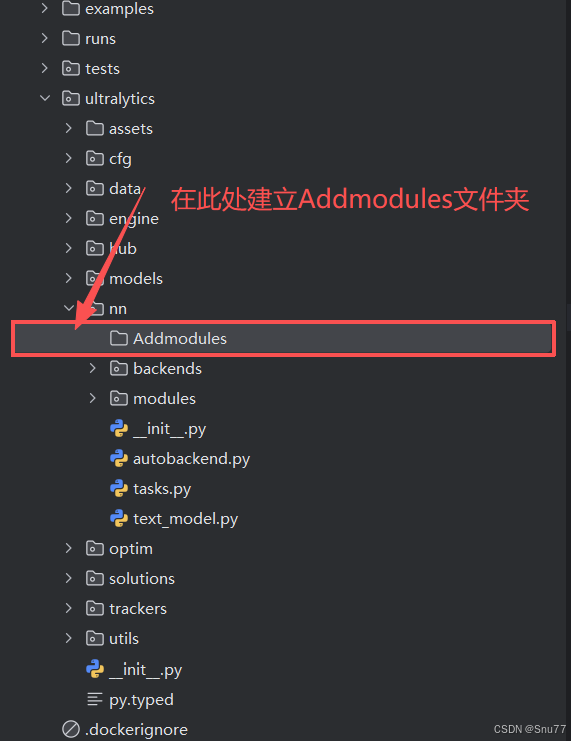
第一还是建立文件,我们找到如下ultralytics/nn文件夹下建立一个目录名字呢就是'Addmodules'文件夹!
4.2 修改二
然后在Addmodules文件夹内建立一个新的py文件,将本文章节三中的“核心代码"复制粘贴进去。

4.3 修改三
第二步我们在该目录下创建一个新的py文件名字为'__init__.py',然后在其内部导入我们的文件,如下图所示。

4.4 修改四
第三步我门中到如下文件'ultralytics/nn/tasks.py'进行导入和注册我们的模块(此处只需要添加一次即可,如果你用我其它的改进机制这里的步骤只需要添加一次)!

4.5 修改五
在'ultralytics/nn/tasks.py'文件内的parse_model方法函数内(位置大概在1500+行左右),按照图示位置添加即可(此处需要自己有一定的判别能力,如果不会可联系作者获得视频教程)。

4.6 修改六
在'ultralytics/nn/tasks.py'文件内的parse_model方法函数内(位置大概在1600+行左右),按照图示位置进行代码的替换即可(此处不改如果你yaml文件中的所有C3k2都被改名了,则检测头会使用老版本的v8检测头参数量会大幅度增加,但不影响运行很多人都忽略了这一步)。
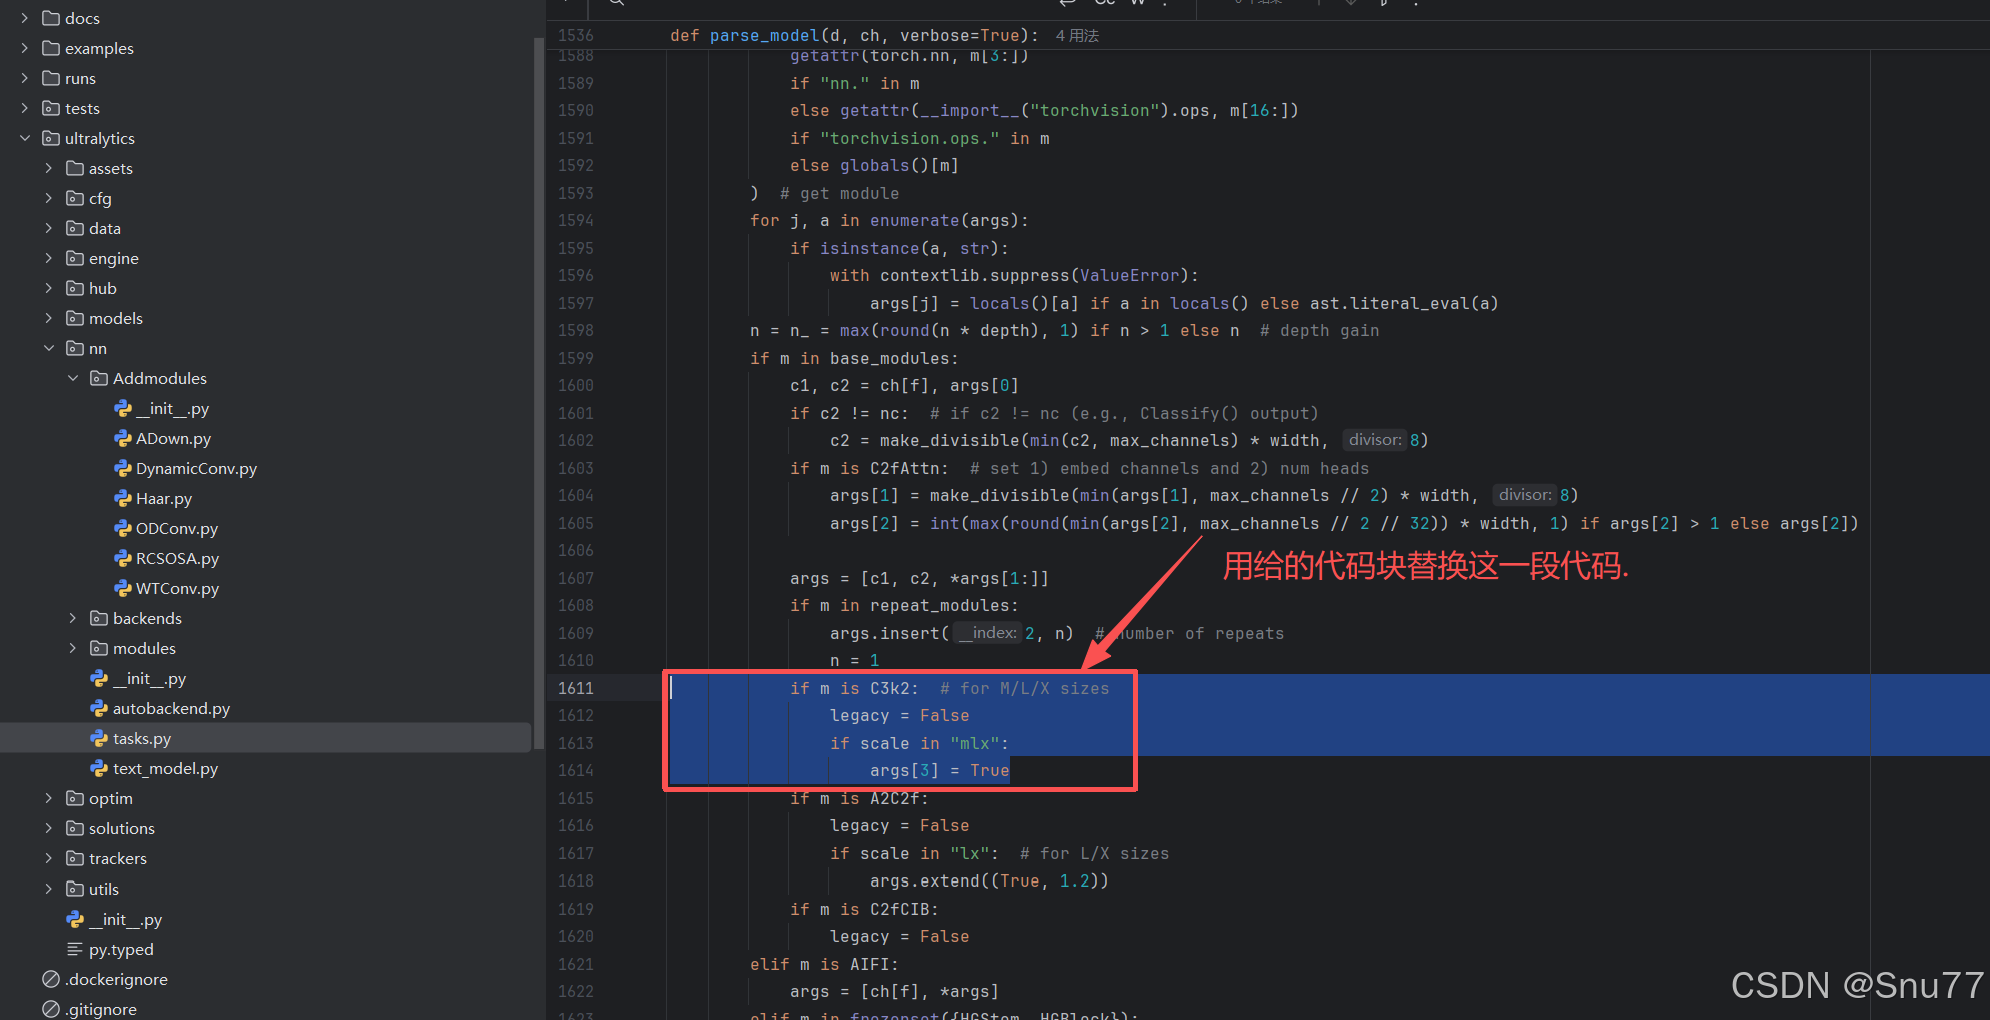
            if "C3k2" in getattr(m, "__name__", str(m)):
                legacy = False
                if scale in "mlx":
                    args[3] = True
到此就修改完成了,大家可以复制下面的yaml文件运行,更多使用方式可以联系作者获得使用视频,本文仅列出常见的使用方式。
五、正式训练
5.1 yaml文件
5.1.1 yaml文件1
训练信息:YOLO26-C3k2-iAFF-1 summary: 387 layers, 2,555,820 parameters, 2,555,820 gradients, 5.9 GFLOPs
# Ultralytics 🚀 AGPL-3.0 License - https://ultralytics.com/license

# Ultralytics YOLO26 object detection model with P3/8 - P5/32 outputs
# Model docs: https://docs.ultralytics.com/models/yolo26
# Task docs: https://docs.ultralytics.com/tasks/detect

# Parameters
nc: 80 # number of classes
end2end: True # whether to use end-to-end mode
reg_max: 1 # DFL bins
scales: # model compound scaling constants, i.e. 'model=yolo26n.yaml' will call yolo26.yaml with scale 'n'
  # [depth, width, max_channels]
  n: [0.50, 0.25, 1024] # summary: 260 layers, 2,572,280 parameters, 2,572,280 gradients, 6.1 GFLOPs
  s: [0.50, 0.50, 1024] # summary: 260 layers, 10,009,784 parameters, 10,009,784 gradients, 22.8 GFLOPs
  m: [0.50, 1.00, 512] # summary: 280 layers, 21,896,248 parameters, 21,896,248 gradients, 75.4 GFLOPs
  l: [1.00, 1.00, 512] # summary: 392 layers, 26,299,704 parameters, 26,299,704 gradients, 93.8 GFLOPs
  x: [1.00, 1.50, 512] # summary: 392 layers, 58,993,368 parameters, 58,993,368 gradients, 209.5 GFLOPs

# YOLO26n backbone
backbone:
  # [from, repeats, module, args]
  - [-1, 1, Conv, [64, 3, 2]] # 0-P1/2
  - [-1, 1, Conv, [128, 3, 2]] # 1-P2/4
  - [-1, 2, C3k2_iAFF, [256, False, 0.25]]
  - [-1, 1, Conv, [256, 3, 2]] # 3-P3/8
  - [-1, 2, C3k2_iAFF, [512, False, 0.25]]
  - [-1, 1, Conv, [512, 3, 2]] # 5-P4/16
  - [-1, 2, C3k2_iAFF, [512, True]]
  - [-1, 1, Conv, [1024, 3, 2]] # 7-P5/32
  - [-1, 2, C3k2_iAFF, [1024, True]]
  - [-1, 1, SPPF, [1024, 5, 3, True]] # 9
  - [-1, 2, C2PSA, [1024]] # 10

# YOLO26n head
head:
  - [-1, 1, nn.Upsample, [None, 2, "nearest"]]
  - [[-1, 6], 1, Concat, [1]] # cat backbone P4
  - [-1, 2, C3k2, [512, True]] # 13

  - [-1, 1, nn.Upsample, [None, 2, "nearest"]]
  - [[-1, 4], 1, Concat, [1]] # cat backbone P3
  - [-1, 2, C3k2, [256, True]] # 16 (P3/8-small)

  - [-1, 1, Conv, [256, 3, 2]]
  - [[-1, 13], 1, Concat, [1]] # cat head P4
  - [-1, 2, C3k2, [512, True]] # 19 (P4/16-medium)

  - [-1, 1, Conv, [512, 3, 2]]
  - [[-1, 10], 1, Concat, [1]] # cat head P5
  - [-1, 1, C3k2, [1024, True, 0.5, True]] # 22 (P5/32-large)

  - [[16, 19, 22], 1, Detect, [nc]] # Detect(P3, P4, P5)
5.1.2 yaml文件2
训练信息:YOLO26-C3k2-iAFF-2 summary: 366 layers, 2,585,276 parameters, 2,585,276 gradients, 5.8 GFLOPs
# Ultralytics 🚀 AGPL-3.0 License - https://ultralytics.com/license

# Ultralytics YOLO26 object detection model with P3/8 - P5/32 outputs
# Model docs: https://docs.ultralytics.com/models/yolo26
# Task docs: https://docs.ultralytics.com/tasks/detect

# Parameters
nc: 80 # number of classes
end2end: True # whether to use end-to-end mode
reg_max: 1 # DFL bins
scales: # model compound scaling constants, i.e. 'model=yolo26n.yaml' will call yolo26.yaml with scale 'n'
  # [depth, width, max_channels]
  n: [0.50, 0.25, 1024] # summary: 260 layers, 2,572,280 parameters, 2,572,280 gradients, 6.1 GFLOPs
  s: [0.50, 0.50, 1024] # summary: 260 layers, 10,009,784 parameters, 10,009,784 gradients, 22.8 GFLOPs
  m: [0.50, 1.00, 512] # summary: 280 layers, 21,896,248 parameters, 21,896,248 gradients, 75.4 GFLOPs
  l: [1.00, 1.00, 512] # summary: 392 layers, 26,299,704 parameters, 26,299,704 gradients, 93.8 GFLOPs
  x: [1.00, 1.50, 512] # summary: 392 layers, 58,993,368 parameters, 58,993,368 gradients, 209.5 GFLOPs

# YOLO26n backbone
backbone:
  # [from, repeats, module, args]
  - [-1, 1, Conv, [64, 3, 2]] # 0-P1/2
  - [-1, 1, Conv, [128, 3, 2]] # 1-P2/4
  - [-1, 2, C3k2, [256, False, 0.25]]
  - [-1, 1, Conv, [256, 3, 2]] # 3-P3/8
  - [-1, 2, C3k2, [512, False, 0.25]]
  - [-1, 1, Conv, [512, 3, 2]] # 5-P4/16
  - [-1, 2, C3k2, [512, True]]
  - [-1, 1, Conv, [1024, 3, 2]] # 7-P5/32
  - [-1, 2, C3k2, [1024, True]]
  - [-1, 1, SPPF, [1024, 5, 3, True]] # 9
  - [-1, 2, C2PSA, [1024]] # 10

# YOLO26n head
head:
  - [-1, 1, nn.Upsample, [None, 2, "nearest"]]
  - [[-1, 6], 1, Concat, [1]] # cat backbone P4
  - [-1, 2, C3k2, [512, True]] # 13

  - [-1, 1, nn.Upsample, [None, 2, "nearest"]]
  - [[-1, 4], 1, Concat, [1]] # cat backbone P3
  - [-1, 2, C3k2_iAFF, [256, True]] # 16 (P3/8-small)

  - [-1, 1, Conv, [256, 3, 2]]
  - [[-1, 13], 1, Concat, [1]] # cat head P4
  - [-1, 2, C3k2_iAFF, [512, True]] # 19 (P4/16-medium)

  - [-1, 1, Conv, [512, 3, 2]]
  - [[-1, 10], 1, Concat, [1]] # cat head P5
  - [-1, 1, C3k2_iAFF, [1024, True, 0.5, True]] # 22 (P5/32-large)

  - [[16, 19, 22], 1, Detect, [nc]] # Detect(P3, P4, P5)
5.1.3 yaml文件3
训练信息:YOLO26-C3k2-iAFF-3 summary: 534 layers, 2,644,108 parameters, 2,644,108 gradients, 6.0 GFLOPs
# Ultralytics 🚀 AGPL-3.0 License - https://ultralytics.com/license

# Ultralytics YOLO26 object detection model with P3/8 - P5/32 outputs
# Model docs: https://docs.ultralytics.com/models/yolo26
# Task docs: https://docs.ultralytics.com/tasks/detect

# Parameters
nc: 80 # number of classes
end2end: True # whether to use end-to-end mode
reg_max: 1 # DFL bins
scales: # model compound scaling constants, i.e. 'model=yolo26n.yaml' will call yolo26.yaml with scale 'n'
  # [depth, width, max_channels]
  n: [0.50, 0.25, 1024] # summary: 260 layers, 2,572,280 parameters, 2,572,280 gradients, 6.1 GFLOPs
  s: [0.50, 0.50, 1024] # summary: 260 layers, 10,009,784 parameters, 10,009,784 gradients, 22.8 GFLOPs
  m: [0.50, 1.00, 512] # summary: 280 layers, 21,896,248 parameters, 21,896,248 gradients, 75.4 GFLOPs
  l: [1.00, 1.00, 512] # summary: 392 layers, 26,299,704 parameters, 26,299,704 gradients, 93.8 GFLOPs
  x: [1.00, 1.50, 512] # summary: 392 layers, 58,993,368 parameters, 58,993,368 gradients, 209.5 GFLOPs

# YOLO26n backbone
backbone:
  # [from, repeats, module, args]
  - [-1, 1, Conv, [64, 3, 2]] # 0-P1/2
  - [-1, 1, Conv, [128, 3, 2]] # 1-P2/4
  - [-1, 2, C3k2_iAFF, [256, False, 0.25]]
  - [-1, 1, Conv, [256, 3, 2]] # 3-P3/8
  - [-1, 2, C3k2_iAFF, [512, False, 0.25]]
  - [-1, 1, Conv, [512, 3, 2]] # 5-P4/16
  - [-1, 2, C3k2_iAFF, [512, True]]
  - [-1, 1, Conv, [1024, 3, 2]] # 7-P5/32
  - [-1, 2, C3k2_iAFF, [1024, True]]
  - [-1, 1, SPPF, [1024, 5, 3, True]] # 9
  - [-1, 2, C2PSA, [1024]] # 10

# YOLO26n head
head:
  - [-1, 1, nn.Upsample, [None, 2, "nearest"]]
  - [[-1, 6], 1, Concat, [1]] # cat backbone P4
  - [-1, 2, C3k2_iAFF, [512, True]] # 13

  - [-1, 1, nn.Upsample, [None, 2, "nearest"]]
  - [[-1, 4], 1, Concat, [1]] # cat backbone P3
  - [-1, 2, C3k2_iAFF, [256, True]] # 16 (P3/8-small)

  - [-1, 1, Conv, [256, 3, 2]]
  - [[-1, 13], 1, Concat, [1]] # cat head P4
  - [-1, 2, C3k2_iAFF, [512, True]] # 19 (P4/16-medium)

  - [-1, 1, Conv, [512, 3, 2]]
  - [[-1, 10], 1, Concat, [1]] # cat head P5
  - [-1, 1, C3k2_iAFF, [1024, True, 0.5, True]] # 22 (P5/32-large)

  - [[16, 19, 22], 1, Detect, [nc]] # Detect(P3, P4, P5)
5.2 训练代码
大家可以创建一个py文件将我给的代码复制粘贴进去,配置好自己的文件路径即可运行。
import warnings
warnings.filterwarnings('ignore')
from ultralytics import YOLO

if __name__ == '__main__':
    model = YOLO('模型配置文件地址,也就是5.1你保存到本地文件的地址')
    # 如何切换模型版本, 上面的ymal文件可以改为 yolo26s.yaml就是使用的26s,
    # 类似某个改进的yaml文件名称为yolo26-XXX.yaml那么如果想使用其它版本就把上面的名称改为yolo26l-XXX.yaml即可(改的是上面YOLO中间的名字不是配置文件的)!
    # model.load('yolo26n.pt') # 是否加载预训练权重,科研不建议大家加载否则很难提升精度
    model.train(
        data=r"数据集文件地址",
                # 如果大家任务是其它的'ultralytics/cfg/default.yaml'找到这里修改task可以改成detect, segment, classify, pose
                cache=False,
                imgsz=640,
                epochs=20,
                single_cls=False,  # 是否是单类别检测
                batch=16,
                close_mosaic=0,
                workers=0,
                device='0',
                optimizer='MuSGD', # using SGD/MuSGD
                # resume=, # 这里是填写last.pt地址
                amp=True,  # 如果出现训练损失为Nan可以关闭amp
                project='runs/train',
                name='exp',
                )
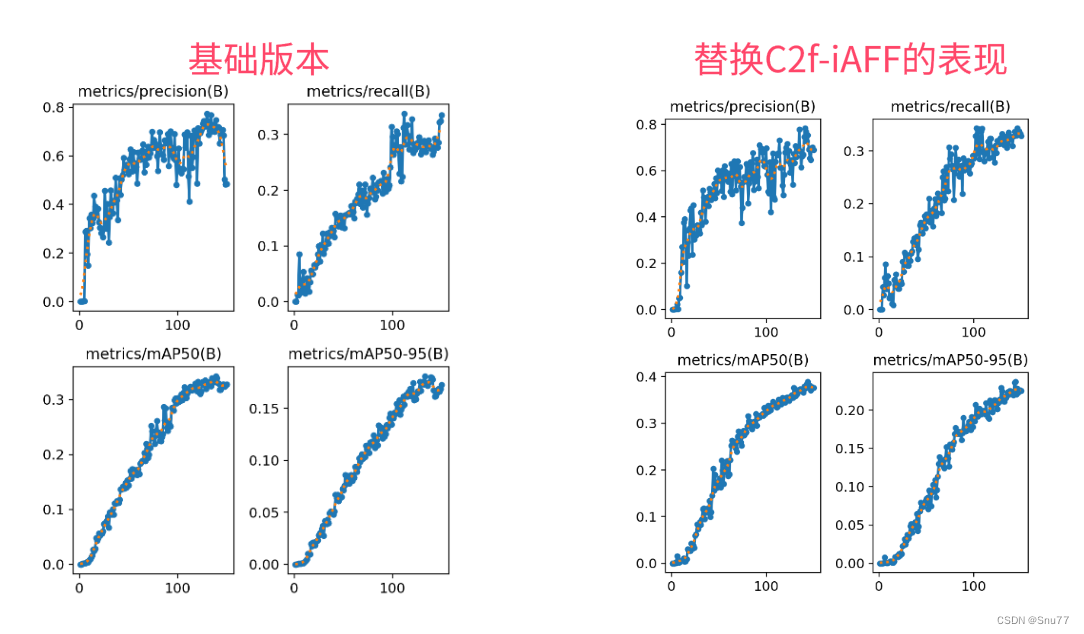
5.3 训练过程截图

五、本文总结
到此本文的正式分享内容就结束了,在这里给大家推荐我的YOLOv26改进有效涨点专栏,本专栏目前为新开的平均质量分98分,后期我会根据各种最新的前沿顶会进行论文复现,也会对一些老的改进机制进行补充,如果大家觉得本文帮助到你了,订阅本专栏,关注后续更多的更新~
专栏链接: