
SpringBoot+spark+scala用spark-submit的方式提交springboot任务
·
前言:
突发奇想,将SpringBoot、spark、scala结合起来然后打成一个jar包,将jar包用spark
一、使用方式
github地址:https://github.com/sgr-china/SpringSpark.git
将项目克隆下来后,把自己本地hdfs-site.xml、core-site.xml、hive-site.xml放到resources目录下,同时按照实际情况修改application.yml后即可运行
项目上还有两个jar包,如果运行时出现冲突则直接用对应的jar包替换spark原来的jar包即可
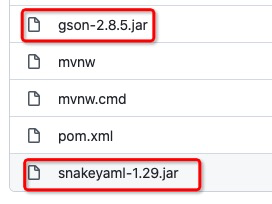
这个项目之前是做了个工具现在单独把这部分拿出来,里面有很多无关的代码不影响使用,主要关注test接口即可,大家也熟悉后可继续修改,其实最主要的就是springboot和spark的结合(pom.xml已修改完毕)
二、代码结构
application.yml
服务的端口、spark相关配置
server:
  port: 30001
  tomcat:
    max-threads: 250
  compression:
    enabled: true

spark:
  app:
    name: SpringSpark
  master:
    uri: local[*]
  driver:
    memory: 1g
  executor:
    cores: 1
    memory: 1g
  num:
    executors: 1
SparkConfig(java)
spark初始化的配置
package com.sgr.conf;

import org.apache.spark.SparkConf;
import org.apache.spark.sql.SparkSession;
import org.springframework.beans.factory.annotation.Value;
import org.springframework.boot.autoconfigure.condition.ConditionalOnMissingBean;
import org.springframework.context.annotation.Bean;
import org.springframework.context.annotation.Configuration;

/**
 * @author sunguorui
 * @date 2021年12月02日 10:40 上午
 */
@Configuration
public class SparkConfig {
    @Value("${spark.app.name}")
    private String appName;
    @Value("${spark.master.uri}")
    private String sparkMasterUri;
    @Value("${spark.driver.memory}")
    private String sparkDriverMemory;
    @Value("${spark.executor.memory}")
    private String sparkExecutorMemory;
    @Value("${spark.executor.cores}")
    private String sparkExecutorCores;
    @Value("${spark.num.executors}")
    private String sparkExecutorsNum;
    @Bean
    @ConditionalOnMissingBean(SparkSession.class)
    public SparkSession sparkSession() {
        SparkConf sparkConf = new SparkConf().setAppName(appName)
                .setMaster(sparkMasterUri)
                .set("spark.driver.memory",sparkDriverMemory)
                .set("spark.executor.memory",sparkExecutorMemory)
                .set("spark.executor.cores",sparkExecutorCores)
                .set("spark.num.executors",sparkExecutorsNum);
        SparkSession spark = new SparkSession.Builder().enableHiveSupport()
                .config(sparkConf)
                .config("spark.debug.maxToStringFields", 1000)
                .getOrCreate();
        return spark;
    }
}
collect(java)
主要关注test接口就好,可继续拓展
package com.sgr.collect;

import com.sgr.serviceScala.ScalaExportService;
import com.sgr.serviceScala.TestScalaService;
import org.hibernate.validator.constraints.NotBlank;
import org.springframework.web.bind.annotation.RequestMapping;
import org.springframework.web.bind.annotation.RequestParam;
import org.springframework.web.bind.annotation.RestController;

import javax.annotation.Resource;

/**
 * @author sunguorui
 * @date 2021年11月21日 9:46 下午
 */
@RestController
public class ExportCollect {

    @Resource
    private TestScalaService testScalaService;

    @RequestMapping("/test")
    public void test(@RequestParam("sql") @NotBlank String sql) {
        testScalaService.getData(sql);

    }

    @Resource
    private ScalaExportService scalaExportService;
    @RequestMapping("/exportT")
    public void testSpark(@RequestParam("sql") @NotBlank String sql,
                     @RequestParam("code") @NotBlank String code,
                     @RequestParam("path") @NotBlank String path) {
       scalaExportService.exportData(sql, code, path, "1000");
    }

}
Service(scala)
把service放在scala下主要是因为操作spark用scala语言比较便利简洁一些
package com.sgr.serviceScala

import com.sgr.conf.LazyLogging
import org.apache.spark.sql.SparkSession
import org.springframework.beans.factory.annotation.Autowired
import org.springframework.stereotype.Service

/**
 * @author sunguorui
 * @date 2021年12月03日 12:27 下午
 */
@Service
class TestScalaService extends LazyLogging{
  @Autowired
  private val sparkSession: SparkSession = null
  def getData(sql: String): Unit = {
    logger.info(sql)
    val df = sparkSession.sql(sql)
    df.show()
    logger.info(df.count().toString)
  }
}
更多推荐

 2
 0
- 0


 已为社区贡献3条内容

所有评论(0)