
一种特殊的rag案例faq
·
rag系列文章目录
前言
rag应用已经有成熟的操作范式,针对具体场景又有一些细微的变化。以电商业务中的问答场景为例,客户积累了大量的问答数据,即faq问答对,这些数据是结构化的,需要再加工处理的步骤不多,非常有利于做rag应用。以下以这种特殊场景为例,简要介绍rag处理步骤。
一、索引生成
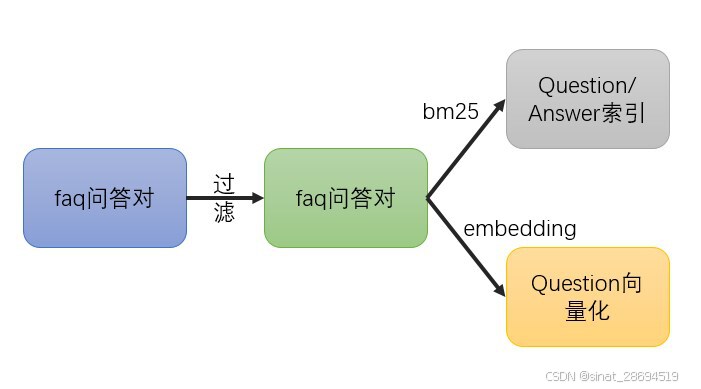
与传统rag应用相比,faq问答对有两点优势
1、 召回数据不需要进行解析切割,可以对faq问答对中的问题和答案,分别进行生成索引,方便进行bm25召回,因为faq问答对是完整的数据,切割会造成不利影响,所以建议不要切割。
2、 向量召回时,仅需要对faq问答对中的问题进行向量化,不需要对faq问答对中的答案进行向量化。客户进行问答时,对query进行向量化,向量匹配召回相似的问题。
Bm25生成索引代码如下
package org.example.util;

import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.FSDirectory;

import java.nio.file.Paths;
import java.util.ArrayList;
import java.util.List;

public class IndexFAQs {
    // 示例数据(实际应从JSON文件读取)
    private static final List<FAQ> sampleFAQs = new ArrayList<>();

    public static void main(String[] args) throws Exception {
        sampleFAQs.add(new FAQ("如何创建索引?", "请参考Lucene官方文档"));
        sampleFAQs.add(new FAQ("如何搜索文档?", "请参考Lucene官方文档"));
        // 索引存储路径
        String indexPath = "index_dir";

        try (Analyzer analyzer = new StandardAnalyzer();
             FSDirectory directory = FSDirectory.open(Paths.get(indexPath))) {

            IndexWriterConfig config = new IndexWriterConfig(analyzer);
            try (IndexWriter writer = new IndexWriter(directory, config)) {
                for (FAQ faq : sampleFAQs) {
                    Document doc = new Document();
                    // 将两个字段分别存储为文本类型,以便搜索
                    doc.add(new TextField("question", faq.question, Field.Store.YES));
                    doc.add(new TextField("answer", faq.answer, Field.Store.YES));
                    writer.addDocument(doc);
                }
                writer.commit();
                System.out.println("索引生成完成,文档数: " + sampleFAQs.size());
            }
        }
    }

    static class FAQ {
        String question;
        String answer;

        public FAQ(String q, String a) {
            this.question = q;
            this.answer = a;
        }
    }
}
二、bm25召回
bm25召回相关faq问答对时,需要检索question和answer两个字段,一般question字段比answer字段更重要,可以设置检索权重大一些,比如3倍,代码如下:
package org.example.util;

import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.queryparser.classic.QueryParser;
import org.apache.lucene.search.*;
import org.apache.lucene.store.FSDirectory;

import java.nio.file.Paths;

public class SearchFAQs {
    public static void main(String[] args) throws Exception {
        String indexPath = "index_dir";
        String queryStr = "文档"; // 示例查询

        try (Analyzer analyzer = new StandardAnalyzer();
             FSDirectory directory = FSDirectory.open(Paths.get(indexPath));
             DirectoryReader reader = DirectoryReader.open(directory)) {

            IndexSearcher searcher = new IndexSearcher(reader);

            // 构建加权查询:question权重高于answer
            QueryParser qpQuestion = new QueryParser("question", analyzer);
            Query questionQuery = qpQuestion.parse(queryStr);

            QueryParser qpAnswer = new QueryParser("answer", analyzer);
            Query answerQuery = qpAnswer.parse(queryStr);

            // 设置字段权重(question权重是answer的3倍)
            Query boostedQuestion = new BoostQuery(questionQuery, 3.0f);
            Query boostedAnswer = new BoostQuery(answerQuery, 1.0f);
            // 组合查询(BooleanQuery)
            BooleanQuery.Builder booleanQueryBuilder = new BooleanQuery.Builder();
            booleanQueryBuilder.add(boostedQuestion, BooleanClause.Occur.SHOULD); // 主要权重
            booleanQueryBuilder.add(boostedAnswer, BooleanClause.Occur.SHOULD);    // 次要权重

            // 执行搜索(返回前10结果)
            TopDocs topDocs = searcher.search(booleanQueryBuilder.build(), 10);

            System.out.println("找到 " + topDocs.totalHits.value + " 条结果:");
            for (ScoreDoc scoreDoc : topDocs.scoreDocs) {
                Document doc = searcher.doc(scoreDoc.doc);
                System.out.printf("问题:%s\n答案:%s\n得分:%.2f\n\n",
                        doc.get("question"), doc.get("answer"), scoreDoc.score);
            }
        }
    }
}
三、向量召回
向量召回时,计算query向量和faq问答对向量的余弦相似度,大于阈值的召回。Faq问答对中问题的长度,和提问的问题长度,差异不大,向量召回更可靠。而一般rag应用向量召回时,使用query向量和切分的chunk向量进行相似度计算,因为长度差异比较大,所以检索效果差一些。
总结
已经存在大量faq问答对的场景,将数据过滤索引后,很容易接入rag系统,进行问答改造。此外,这类问答场景中,客户问题一般也具有某种共性,可以提取一些规则,基于规则匹配faq问答对,提高召回数据准确性。
更多推荐



 5
 0
- 0


 已为社区贡献1条内容

所有评论(0)