
解决 pytorch 报错 RuntimeError: An attempt has been made to start a new process...
·
报错信息
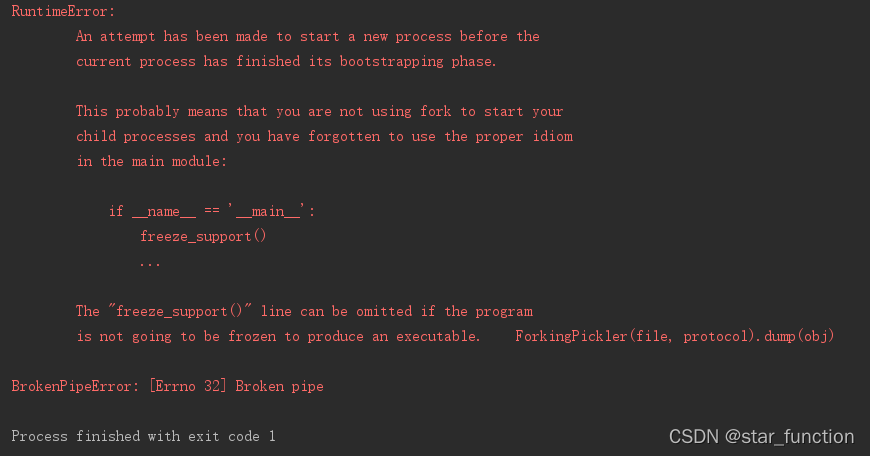
运行 pytorch 代码报错,BrokenPipeError: [Errno 32] Broken pipe,看起来和多线程有关。
RuntimeError:
        An attempt has been made to start a new process before the
        current process has finished its bootstrapping phase.

        This probably means that you are not using fork to start your
        child processes and you have forgotten to use the proper idiom
        in the main module:

            if __name__ == '__main__':
                freeze_support()
                ...

        The "freeze_support()" line can be omitted if the program
        is not going to be frozen to produce an executable.    ForkingPickler(file, protocol).dump(obj)

BrokenPipeError: [Errno 32] Broken pipe
原因分析
pytorch 加载数据集时会使用到 DataLoader 方法,其中参数 num_workers 为加载数据集所用的线程数量。线程数越多,数据集加载越快。
dataloaders = {x: torch.utils.data.DataLoader(image_datasets[x], batch_size=opt.batchsize,
                                             shuffle=True, num_workers=2, pin_memory=True) # 8 workers may work faster
              for x in ['train', 'val']}
layumi 在 issue 中也提到 Windows 下 pytorch 对多线程的支持不够好。
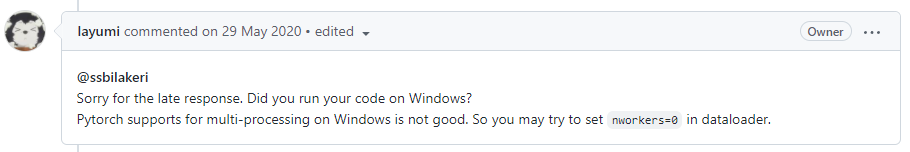
由于报错信息与多线程有关,因此考虑将 num_workers 设为 0,或者去掉该参数。
解决办法
- 去掉 num_workers 参数
dataloaders = {x: torch.utils.data.DataLoader(image_datasets[x], batch_size=opt.batchsize,
                                             shuffle=True, pin_memory=True) # 8 workers may work faster
              for x in ['train', 'val']}
- 将 num_workers 设为 0
dataloaders = {x: torch.utils.data.DataLoader(image_datasets[x], batch_size=opt.batchsize,
                                             shuffle=True, num_workers=0, pin_memory=True) # 8 workers may work faster
              for x in ['train', 'val']}
参考链接
更多推荐

 0
 0
- 0


 已为社区贡献7条内容

所有评论(0)